Lead Analysis
Inkling 2 Small: Apache 2.0 open-weights model that resets enterprise cost assumptions
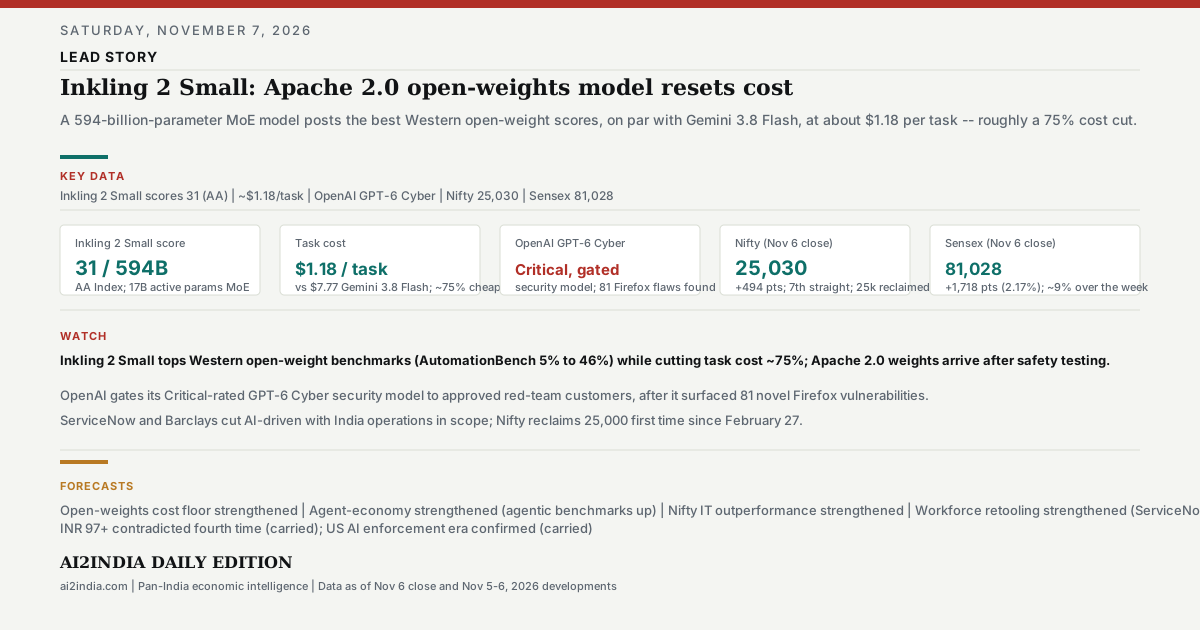
Saturday, November 7, 2026: Thinking Machines has released Inkling 2 Small, a 594-billion-parameter mixture-of-experts model that posts the best benchmark scores of any Western open-weight release and cuts task cost roughly 75% — an Apache 2.0 option for Indian enterprises that want open, deployable weights.
Led by former OpenAI CTO Mira Murati, the startup trained the model on a strikingly compact run — about 12 trillion tokens, with reinforcement learning on just 3 trillion over nine days on 2,048 GPUs — and plans to release full weights under Apache 2.0 once external safety testing wraps up.
Inkling 2 Small scores 31 on the Artificial Analysis Intelligence Index, an 18-point jump over its predecessor and roughly on par with Gemini 3.8 Flash. Its gains are concentrated where enterprises deploy agents: AutomationBench-AA leaps from 5% to 46%, FrontierCode 2.0 from 5% to 25%, and the knowledge-work benchmark AA-Briefcase hits 1,527 Elo, 615 points above the prior model. It also posts the highest vision and document scores among open-weight models, including 81.6% on MMMU Pro and 64.7% on PerceptionBench.
The pricing story is the one Indian buyers will weigh first. At about $1.18 per task, Inkling 2 Small costs roughly a sixth of Gemini 3.8 Flash ($7.77) and a twelfth of Claude Sonnet 5.5 ($10.02), according to Artificial Analysis — landing near low-cost Chinese models while out-scoring every Western open-weight release it was measured against. That is a direct reset of the cost-of-intelligence curve for any Indian team pricing agent workflows or document pipelines.
The Apache 2.0 licence is the structural signal. Unlike the more restrictive open weights from other major labs, Apache 2.0 permits fine-tuning, redistribution and commercial embedding with minimal obligations — the licensing posture Indian BFSI, government and GCC estates most want for on-premises or regulated deployments. Weight release has not happened yet, so the promise is real but conditional on the pending safety review; inference and fine-tuning are available on the Tinker platform today.
Two caveats matter for adopters. The model is only available through Tinker until the weights ship, and its higher token usage — about four times its predecessor per task — means operators must measure cost by total task spend, not per-token list price. It also does not support audio and is weaker on chat, so it is a specialised workhorse, not a general assistant. For Indian enterprise planners, the takeaway is a new ceiling on Western open-weights capability and a new floor on cost simultaneously.
The launch lands as Indian markets extend a seventh straight rally, with Nifty reclaiming 25,000 for the first time since February 27 on November 6 — Sensex +1,718 to 81,028 and Nifty +494 to 25,030, with the AI-services complex and banks leading. The sequence of sub-day open-weights releases and steep price cuts across the autumn reinforces the same trade for Indian IT and GCC buyers: models get cheaper and more deployable, so the differentiation moves to data, integration and the enterprise layer built on top.